Runtime: String.Equals() and == Perf Issue in .NET Core
I have found a perf issue when comparing strings with Equals() and == in .NET Core. When compared to .NET 4.8, Core 2.2 is less performant and Core 3 is even slightly less performant than 2.2.
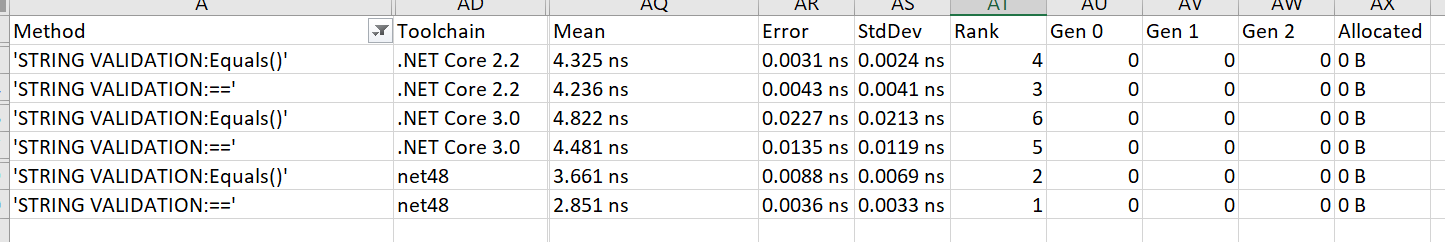
Examples:
testWord1.Equals(this.testWord2)
testWord1 == testWord2
Benchmark project located here: https://github.com/RealDotNetDave/dotNetTips.Benchmark.App
 RealDotNetDave
>All comments
These numbers are expected. Your benchmark only tests the cases where the strings have the same length but where the first character of each string is not equal. In previous versions of .NET, string equality was a char-by-char comparison, so a difference in the first char would be quickly detected. Such is the case with the specific testWord1 and testWord2 values in your benchmarks.
.NET Core 3 instead reads entire chunks of the strings at a time and compares every character in those chunks simultaneously. (This is called "vectorization" in the code base.) On the whole, this tends to make equality comparison much, _much_ faster since we can process more data at once. If you modify your benchmarks such that the two strings being compared have the same contents, or if the first "different" char is moved to position 2 or 3 instead of position 0, you should see this improvement reflected in your numbers.
Since everything is a trade-off, our use of vectorization in this code does incur a slight perf hit in the scenario where the first char or two in the string is different. However, as your benchmark shows, this cost is less than 2 ns per invocation on your machine. This is why we believe it to be an acceptable trade-off.
 GrabYourPitchforks
on 15 Sep 2019
Related issues
 iCodeWebApps
·
3Comments
 aggieben
·
3Comments
 noahfalk
·
3Comments
 matty-hall
·
3Comments
 jzabroski
·
3Comments
Most helpful comment
These numbers are expected. Your benchmark only tests the cases where the strings have the same length but where the first character of each string is not equal. In previous versions of .NET, string equality was a char-by-char comparison, so a difference in the first char would be quickly detected. Such is the case with the specific
testWord1andtestWord2values in your benchmarks..NET Core 3 instead reads entire chunks of the strings at a time and compares every character in those chunks simultaneously. (This is called "vectorization" in the code base.) On the whole, this tends to make equality comparison much, _much_ faster since we can process more data at once. If you modify your benchmarks such that the two strings being compared have the same contents, or if the first "different" char is moved to position 2 or 3 instead of position 0, you should see this improvement reflected in your numbers.
Since everything is a trade-off, our use of vectorization in this code does incur a slight perf hit in the scenario where the first char or two in the string is different. However, as your benchmark shows, this cost is less than 2 ns per invocation on your machine. This is why we believe it to be an acceptable trade-off.