Runtime: System.Data.Odbc.OdbcParameterCollection.Add Slow
I have a project which adds thousands of parameters to an OdbcCommand for bulk inserts.
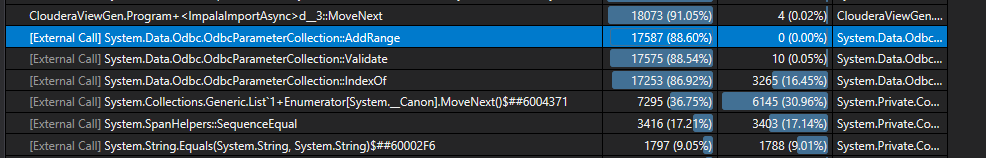
Testing shows that OdbcParameterCollection.Add() and OdbcParameterCollection.AddRange() are both very slow methods.
Jumping into the profiler it seems these methods spend most of their time in Validate():
Is there anything that can be done to improve the performance here?
 pgodwin
All 11 comments
Workaround found.
The code for creating the parameter looked as follows, note the length of the name is 0.
var param = new OdbcParameter("", odbcType);
The causes void Validate() to build a name until it find one that isn't taken. This is fine for small collections, but is very slow for large collections.
if (0 == name.Length)
            {
                index = 1;
                do
                {
                    name = ADP.Parameter + index.ToString(CultureInfo.CurrentCulture);
                    index++;
                } while (-1 != IndexOf(name));
                ((OdbcParameter)value).ParameterName = name;
}
IndexOf(name) isn't exactly fast - so it spends all it's time in there.
The workaround is simply to give the parameter a name:
var param = new OdbcParameter((b * i).ToString(), odbcType);
and now the code is much faster!
Perhaps this could be improved at the library level?
pgodwin
on 15 Feb 2019
A few thoughts:
I noticed that the same logic exists for SqlClient at https://github.com/dotnet/corefx/blob/f40cb8ea05d8b1f3d9acdcd8cf257c764ef56693/src/System.Data.SqlClient/src/System/Data/SqlClient/SqlParameterCollectionHelper.cs#L276-L307, so this likely isn't just affecting System.Data.Odbc. I assume this was originally in shared implementation code.
Although it is obviously intended to work, I am not sure how common creating parameters with an empty name really is. @pgodwin I would like to learn more about why you did it.
I assume you have to have a large number of parameters for this to start to matter, though not sure how many. We do want to support large numbers of parameters but I suspect smaller numbers are significantly more common. @pgodwin again, it would be good to know how many parameters you have in the parameter collection and why.
I can think of a simple way to optimize this code but I suspect more "normal" usage (fewer parameters, specifying a name) would pay a price. My reasoning is:
- I don't think there is a completely safe way to synthesize unique names that doesn't entail performing a lookup.
- If we want to accelerate the lookup we could use a dictionary instead of a list, but it sounds like that would add overhead for simple usages.
- We could choose to defer the creation of the dictionary until some threshold (e.g. some number of lookups) is hit, but then the code becomes more complex, and it isn't clear to me that it is worth it.
@roji @ajcvickers what do you think?
 divega
on 16 Feb 2019
I don't think there is a completely safe way to synthesize unique names that doesn't entail performing a lookup.
Guids? but I don't think it's a good idea.
Adding thousands of parameters feels like a very strange thing to do. Why would you need that many?
 Wraith2
on 16 Feb 2019
Lots of parameters can make sense when you're doing batched bulk inserts (as @pgodwin wrote above) - a single DbCommand with many INSERT statements. Of course a specialized bulk copy is much better for this, but I suspect no such thing exists for ODBC specifically; so this seems like it would be more of a problem for ODBC than for SqlClient. However, it's conceivable to also batch other types of statements so this probably shouldn't be dismissed too quickly.
@divega FWIW Npgsql has exactly this kind of trick, where for a low number of parameters a simple list is used, but once a certain threshold is passed a dictionary is used instead for better perf. The threshold is currently 5, but to be honest I haven't given this any attention so far, so it may very well be working badly. We need to do some benchmarking here to get a clear idea.
One more thought: with the new batching API design (#35135), this should become much less of a problem. The reason is that you no longer have a single DbCommand with a huge list of parameters, but rather many DbCommands in a DbCommandSet, each managing its own parameter list (that's another reason I never liked concatenation-based batching). Once this issue goes away, I think it's really hard to imagine a single-command, single-statement scenario with a huge number of parameters...
 roji
on 16 Feb 2019
@divega The lack of names is due to ODBC parameterized commands not using parameter names. Ie where F1=?, F2 = ?. As far as I can tell it just ignores the names and uses the index of the parameters.
@wraith2 The use of such a large number of parameters is to populate an INSERT statement with hundreds of rows on a wide table. The ODBC driver (Impala ODBC) has an optimisation for many records in a single insert.
pgodwin
on 16 Feb 2019
I see, so it is a strange thing to do and it's caused by Odbc limitations. I'd say you've hit on the best solution by naming them yourself in that case. The Validate method could be made to detect empty names and replace them with something like "_" + Guid.NewGuid().ToString() indicating an internal name and uniquing it.
In SqlClient i'd approach this using a table valued parameter, I've been working on improving their performance for bulk inserts like this.
Wraith2
on 16 Feb 2019
While the number of parameters is due to ODBC limitations, we are talking about the Odbc client so it might be more common than it first appears.
But the simple workaround of specifying a name is fine from my point of view. Maybe a remark could be added to OdbcParameter docs to mention a name is recommended in cases of a large number of parameters?
pgodwin
on 16 Feb 2019
Notes from System.Data triage:
- Implementation to avoid a linear search when there are many parameters seems worthwhile.
- Based on previous agreement, System.Data.Odbc is owned by SqlClient team and the issue also affects SqlClient, so putting it in that area.
 ajcvickers
on 25 Feb 2019
Is this still being worked on for 3.0? Is the perf issue here unique to .NET Core, or is it similar for .NET Framework? Is it a regression from .NET Core 2.2?
 stephentoub
on 9 Jul 2019
I think we should move to future. @ajcvickers, @roji, thoughts?
divega
on 9 Jul 2019
Agree, we're probably not going to have a bandwidth to take care of this for 3.0.
@stephentoub IIRC this isn't a regression from .NET Core 2.2, the same issue exists there. Same for .NET Framework according to the reference sources.
@divega do we have an issue tracking this on https://github.com/dotnet/sqlclient?
roji
on 9 Jul 2019
Related issues
 jkotas
·
3Comments
 omajid
·
3Comments
 jchannon
·
3Comments
 GitAntoinee
·
3Comments
 btecu
·
3Comments
Most helpful comment
Workaround found.
The code for creating the parameter looked as follows, note the length of the name is 0.
The causes
void Validate()to build a name until it find one that isn't taken. This is fine for small collections, but is very slow for large collections.IndexOf(name)isn't exactly fast - so it spends all it's time in there.The workaround is simply to give the parameter a name:
and now the code is much faster!
Perhaps this could be improved at the library level?