Runtime: SSLStream suffers degraded performance on Unix when completing writes sync
If you make the write side of SslStream at any point in the code swap contexts/threads and reschedule you get a ~4x speed increase from plaintext tests on Kestrel.
After looking at the CPU use and stats it would point towards a lock contention/deadlock scenario. As the number of threads/connections goes up the overall CPU use goes down quickly.
We have tried replacing the PinnableBuffer pool for an ArrayPool and that made a small difference (a few percent but not enough to worry about)
I will perform some more investigation and see if I can at least narrow the issue.
 Drawaes
All 35 comments
@stephentoub @geoffkizer
(Thanks to @benaadams for the ideas and keeping me sane at 4am doing c++ )
So after much testing and nashing of teeth I have a solid theory of what is going on.
Current Behaviour - A tale of concurrency
On Unix only we see an inability to scale up to extreme throughput on SslStream. This is not the case on Windows. Ben has been testing on both Windows and Unix on 32 thread/core (not sure what an Azure "core" actually is) machines and the different is stark. With this knowledge I have eliminated Windows from the investigation completely.
The issue we see is that if we push off onto a seperate continuation at anypoint during the write cycle on SslStream (encrypting data) we see a significant throughput increase. However there are some interesting facts around this
- Geoff clearly showed that in a small core count test, using a continuation hurt performance (which is what we would expect in all situations).
- We saw that using a small number of connections (from 5) up until a medium number (about 10) we saw near linear scaling in performance, but then it topped out, dropped off for a while and then just leveled out.
This was the first hint that we had a contention issue. The server I am testing with is a NUMA 2 socket 12 core per socket Xeon. During any benchmark I struggled to hit high CPU use which I found strange as I would expect the AES functions (dispite acceleration) to take the majority of the time. I put it down to issues with my older Infiniband cards not doing server side scaling correctly, however this was an early warning sign that I missed.
After a fair amount of investigation into the issue and several different tracing tools later, I have the following evidence
(the measurements are suffering badly from the observer effect due to tracers causing the kernel calls to slow)
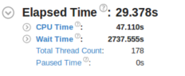
As we can see the wait time is “terribad” to borrow someone elses term.
Drilling into it, we can see the problem is
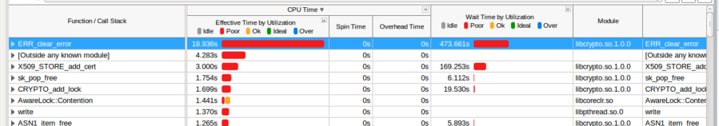
Pretty clear, ERR_clear_error. Which belongs to OpenSsl
Removing a 2 of the calls in the Ssl PAL to ERR_clear_error gets us from 150k rps to 600k rps with no other changes.
So why is that method causing so many problems?
Let me give you a quick rundown of OpenSsl locking (TLDR; it’s not pretty)
OpenSsl has pretty coarse locking, based on “type” rather than instances of types. Errors are stored per thread in a hashtable of threadid’s. This is a hashtable of queues. This hashtable is “global” and has a single mutex protecting it. Every call to set an error, look at an error (including peek) or clear errors takes a lock on this global mutex. That is what we are seeing above.
Also accessing the queue creates a queue on the thread (thus allocating memory) which we might never need. Which is a known potential leak (can OpenSSL track the destruction of .net threads, if not it can’t clean that up).
So as we backup on this mutex we get the threadpool creating threads (because we can’t service the requests with the threads we have so the hill climbing kicks in) and that of course makes the situation worse. In a 15 second test I can hit ~130 threads most of which are waiting.
Interesting points
Points for extra credit, the PR with the continuation, fixed the problem a little by ramming in a bunch of context switches slowing down the inevitable lock convoy.
Low process count machines will never show this problem up, the value of large scale testing showing up here 😊
In my “prototype” libraries that I have gone back and checked I saw less of this effect because my locking was done in a c# callback that used light weight userspace managed locks
FYI I have also tried the following
Using pthread R/W locks == worse
Using pthread SpinLocks == 150k -> 200k but nothing to write home about.
So what can we do about it?
There are a few options the way I see it.
- Move to OpenSsl 1.1, they implemented the error queues as thread local storage to stop this exact issue. This has it’s own set of issues, mainly that I imagine there are plenty of distros/IOT etc that just won’t support a hard move.
- Move to BoringSsl ... they fixed it during the fork.. but see 1. For the issue
- Try a reader/writer lock as OpenSsl has that concept -> did that and if you read the OpenSsl code you can see they basically always ask for a write lock, which is a shame because Futexs are quick for many uncongested readers... but no dice
- Fix OpenSsl in your own patch, (Akami seems to have done this a few years back for this issue), but it’s not really feasible for a framework to do.
- Leave it as is... Terribad
- Remove the ERR_clear_error calls ... this is the best short term option but let’s discuss it below....
So the problem with removing the ERR_clear_error is that if something else put another error on the queue we will get the wrong result during the AsyncIO on OpenSsl. But this might not be a problem and here is why.
There are two potential outcomes from the wrong error, a false positive and false negative. So for a false positive we think it’s an error, when it isn’t and close the connection without cause. As this is a super rare event I think in a security library, terminating a connection isn’t a big deal. The user/application reconnect and job done no harm no fowl.
The issue comes if say a previous call puts a “Needs Read” on the queue, throws an exception for what ever reason (say a write to the underlying socket) and dies. The thread is recycled by the AppPool and proceeds to process a different connection. That returns an actual error and we say okay lets check the queue, it’s says needs read so we use the SslContext to do a read. The context is actually now in an invalid state and the behaviour is “unknown”.
This in security is not good, we are operating on an unmanaged struct storing a statemachine when we should have terminated the connection.
There is a way to mitigate this however, if we go with my original PR with a few modifications we can put a flag on the read/write BIO that we clear before an operation (effectively our own error state but without the nasty global lock). Then we set in the BIO that we needed to read or write during the operation because we will know. And then if the Ssl operation returns and error, we retrieve the error code and check for a match on the managed BIO side. If they match we proceed, if they don’t we fail. This was we might have a small number (like I have never seen it in a few 100m connections) of false positives (false errors) but never a false positive (everything is cool when it isn’t).
One last way to get a little bit of perf is to lock inside the encrypt/decrypt call so that the stream only does one side and as this is a local lock it will reduce the contention there but it’s really a nasty hack.
So if you agree, I will go back to my PR and make some adjustments, and see what we can do.
As a last note if we are really careful to never need a “needs write, needs read” by using the arraypool then we should pretty much avoid the error queue lock completely and be able to speed ahead, so I might even be able to get faster still now 😉
Thoughts?
(It’s been an real, over to you😝)
Drawaes
on 24 Aug 2017
Thanks for the excellent investigation here.
Re this:
The issue comes if say a previous call puts a “Needs Read” on the queue, throws an exception for what ever reason (say a write to the underlying socket) and dies.
Can we simply ensure that whenever we get an error from an OpenSsl call, we immediately retrieve the error(s)? We can do this at the very lowest level (native code) so that we feel confident that this is actually enforced reliably.
I will defer to @bartonjs on how possible it is to move to a different version/library.
 geoffkizer
on 24 Aug 2017
Maybe, but there are issues with that potentially, first the man pages explicitly say you need to call clear to be sure. Also on 5 year old naggle forums people complain about odd errors occasionally ... if they didn't clear
Drawaes
on 24 Aug 2017
also, the openssl is shared and you have to ensure that EVERY call collects its errors, even if there is an exception.... not sure it's something I would commit to.
Drawaes
on 24 Aug 2017
Put it this way,
You call a function, internally it calls another function (say on a BIO). That causes an error and then the upper function puts an error in the queue as well then returns to your code.
Now you pop an error, but you left one on the queue. So what do you do? Clear the queue, now we are looking at two queue ops... which has the same concurrency issue, remember that the error queue is often used to signal "state" in openssl because... it's openssl :P
Drawaes
on 24 Aug 2017
Yeah, this all seems messy. Yuck.
geoffkizer
on 24 Aug 2017
Yeah not how i would have done it :)
Drawaes
on 24 Aug 2017
I will defer to @bartonjs on how possible it is to move to a different version/library.
We'll need to start working to support OpenSSL 1.1 soonishly, as distros are starting to move. We can't really enforce it as a minimum, and our portable build will need to do whatever our minimum is.
Moving to a different library (different than OpenSSL) is "no" (several (9ish) months of work, might make portable harder, might box us out of our current target distros, etc).
Can we simply ensure that whenever we get an error from an OpenSsl call, we immediately retrieve the error(s)?
We do. But sometimes a call that succeeded left some error state sprinkled on the queue, so when we think something bad happened and we prep an exception it says "yep, there's an error here" and we throw some leftover/ignored error.
We've actually added ERR_clear_error() calls to make weird exceptions go away.
It's possible that we're locking and unlocking too much, around the error queues (if each call locks) and that what we want to do is try to bulk up some operations to one lock. More code inside the critical section but fewer entrances and exits, sometimes that's a win. But that's just a conjecture.
 bartonjs
on 25 Aug 2017
These are not your locks, these are OpenSsl's locks, not much you can change unless you change openssl which is not really a go :)
Drawaes
on 25 Aug 2017
We can call CRYPTO_lock(locktype) in the shim before doing a series of operations, and CRYPTO_unlock on the way out.
bartonjs
on 25 Aug 2017
By default the pthread mutexes aren't re-entrant. We could change that I guess, but it again will hurt perf elsewhere. I can benchmark it though. (unless there is somewhere you are changing the default but from what I can see you are using init(pointer, null) with the null being default settings.
Drawaes
on 25 Aug 2017
PTHREAD_MUTEX_NORMAL
      This  type  of  mutex  does not detect deadlock. A thread attempting to relock this
      mutex without first unlocking it shall deadlock.   Attempting  to  unlock  a  mutex
      locked by a different thread results in undefined behavior. Attempting to unlock an
      unlocked mutex results in undefined behavior.
Fair enough. So then it sounds to me like "it is what it is" and our best takeaway is to try to get to "supporting" OpenSSL 1.1, and then figure out what it means to stop supporting OpenSSL 1.0.x. ./build-native.sh -portable=false on a system that has the 1.1 headers will let someone start tackling all the places that we don't compile anymore due to the breaking API/ABI changes.
bartonjs
on 25 Aug 2017
If someone can make a branch and sort out someway to make a build work (as in the cmake and magic) I am happy to patch the breaking changes.. but me and cmake aren't good buddies :P
Drawaes
on 25 Aug 2017
Right so I have tried
Every type of Pthread/lock I can, with every protocol. Nothing helps, expanding the critical section just hurts because the Clear Error and the look for error are before and after the actual encrypt call so you serialise the CPU bound bit.
I do have a solution though.... it's good and bad news. Good news we can fix this with 1.0x and I am back up to 850k ish without any optimisations. Good news it's something that @stephentoub has been hinting at for a while.
Bad news, it probably needs the internals to go to Async/Await to keep things sane.
The problem refined
So we bank up behind these mutexes which all release in one bang, wake all the waiters and they compete and lock again, classic convoy.
And the threadpool kicks in "hey cpu use is low and I have no threads lets make some more".
So I have prototyped changing the write side only at this stage to async/await and it's not optmised for the "hot path" much at all so we have room. But then we can put in a semiphore slim. We can only ever at max encrypt or decrypt core count things anyway, so we either take the lock and enter and thus relieve a lot of pressure. If we need to wait because its an Async lock we can return the thread to the threadpool and queue the next requests.
So the threadpool doesn't get out of hand, the mutex doesn't get into a convoy and life is good. We can also "pal" this out by having a method or something that returns nothing on the windows case but a cached completed task so shouldn't hurt other than an if.
Thoughts? because I don't really want to bang away on this if it's a non starter?
Drawaes
on 25 Aug 2017
If I'm understanding correctly, it makes sense to me. @geoffkizer? @bartonjs?
 stephentoub
on 26 Aug 2017
Just to make sure I understand: We add a semaphore so that instead of blocking in OpenSsl, the threadpool threads will instead await the semaphore before taking the OpenSsl lock and thus return the thread to the threadpool, avoiding starvation and convoy issues.
That sounds good to me.
I don't think you need to fully convert to async/await to make this happen. I wrote some code previously to help convert from Task to the internal AsyncProtocolRequest stuff that may be useful. It allows you to write a portion of the code using Task, then convert that to AsyncProtocolRequest for existing code that's written in terms of it. Code here: https://github.com/dotnet/corefx/blob/cb173f6004e9671793d1aff64bab78e2d5f701c3/src/System.Net.Security/src/System/Net/Security/SslStreamInternal.cs#L557
geoffkizer
on 26 Aug 2017
BTW, converting the existing async logic to Task/await is a good thing to do regardless; but it needs to be done carefully or we'll introduce perf regressions.
geoffkizer
on 26 Aug 2017
I don't see a problem with it. Not sure I quite follow, but no red flags; and it'll probably make more sense to me in code :).
bartonjs
on 26 Aug 2017
Fair enough. I will write some pseudo code in here first later today. Then if we agree on the direction ( APM or async or whatever implementation) then I can start doing some code proper
Drawaes
on 26 Aug 2017
@bartonjs
Pseudo code would be something like (ignoring APM, optimisations, and moving this out to the PAL to avoid it on windows, osx, although it might be worth benching on those because its a CPU bound operation that the threadpool has little visibility into and we might find there are other hidden locks :0 )
private static SemaphoreSlim s_lock = new SemaphoreSlim(Environment.ProcessorCount /2);

public async Task WriteAsync(byte[] buffer, int offset, int count)
{
    //Normal checks and balances to make sure data and state is good
    //And no nested writes, and error handling
    if(!s_lock.Wait(0))
    {
        await s_lock.WaitAsync();
    }
    try
    {
        DoEncryptionAndOpenSslStuff(inbuffers, outbuffers etc);
    }
    finally
    {
        s_lock.Release();
    }
    await innerStream.WriteAsync(outbuffer);
}
So that has the effect that if there is less than numproc/2 calls you will get through for almost free (should just be an interlock operation). If there is more instead of the convoy happening and the thread pool firing up more threads to do other busy work, the thread will be released and the request queued up.
(FYI I struggle to understand things without a code example :) )
Attribution : The locking pattern was "borrowed" from one @benaadams ... shoulders of giants and all.
Drawaes
on 26 Aug 2017
I think the best approach here then is to do a series of smaller PR's that change a specific piece leading up to the ability to make a significant change from APM (or maybe not) but so the code becomes less complex in the process of making this change. Currently the SslStream -> SslStreamInternal -> SslState -> SecureStream -> Pal -> Interop -> C ++ Pal layering on top of the Pinnable buffer custom class and 900 lines of APM just in the SslStreamInternal make it somewhat unapproachable without spending hours getting your head around it.
Adding more methods to the APM side unless we can show that Async/Await just can't perform is just going to make the cognitive load of these classes higher and higher. Which isn't ideal to get others involved in perf, but to also reason about flow/security behaviour.
With that in mind I have started it with this PR
dotnet/corefx#23572
I will track progress towards the above solution in this issue and then close once I think we are there... cool?
Drawaes
on 26 Aug 2017
I think the best approach here then is to do a series of smaller PR's that change a specific piece
+1. Thanks.
stephentoub
on 27 Aug 2017
@Drawaes, how close are you to tackling this one? Seems like since you've already successfully turned the write path into one that uses tasks and async/await, it should be fairly straightforward? If you don't think we'll be successful in getting a real fix in quickly, what would you think about putting in a temporary hack that just adds the dummy continuation we saw previously bred most of the wins, simply to bank the gains and tide us over until this real fix can be put in place?
stephentoub
on 10 Nov 2017
In theory the read and the write side suffer the same issue. I was waiting for the read side then it would have slotted in nicely, but that got a bit derailed by other PR's and then I got busy at work for the last 2 weeks :). I was going to look at that re-occurring error over the next 2 days because I want to be confident that things haven't become unstable but that could take a while.
Let me take a look at the read side again now, and if I can get it sorted this weekend, then a proper fix should be simple (Semaphore slim, and we are async so we can just Wait(0) then WaitAsync so basically free for the non contested case). If I don't think I can get the read side in easily then we can just jam in a continuation, but I wonder about thread starvation in ASP.NET if we do that?
Drawaes
on 10 Nov 2017
I wonder about thread starvation in ASP.NET if we do that?
Why would that impact starvation? It's extra overhead, yes, but just another empty work item to go through the queue, no extra blocking, etc. I don't love adding such overhead, but when it buys us massive scalability wins as a temporary workaround, I'm ok with it.
we can just Wait(0) then WaitAsync
You should just be able to WaitAsync... there shouldn't be a need for the Wait(0). In fact on core I'd expect that to be slower.
Let me take a look at the read side again now
Ok, thanks.
stephentoub
on 10 Nov 2017
You should just be able to WaitAsync... there shouldn't be a need for the Wait(0). In fact on core I'd expect that to be slower.
Looking at code, is faster for for fail fast - likely could tweak to be the same.
No items 1M iters
| method | fail (ms) |
| --- | --- |
| Wait(0) | 12.28 |
| WaitAsync(0) | 24.38 |
But slower for success as the WaitAsync just does its thing; whereas Wait has to check for async waiters.
Aside: My patterns have just leveled up...
// Without timeout
var aquireTask = _semaphore.WaitAsync();
if (!aquireTask.IsCompletedSuccessfully)
{
    await aquireTask.ConfigureAwait(false);
}
// With timeout
bool sucess;
var timeoutTask = _semaphore.WaitAsync(TimeSpan.FromSeconds(1));
if (timeoutTask.IsCompletedSuccessfully)
{
    success = timeoutTask.GetAwaiter().GetResult();
}
else
{
    success = await timeoutTask.ConfigureAwait(false);
}
So...
Task DoAsync()
{
    var aquireTask = _semaphore.WaitAsync();
    if (!aquireTask.IsCompletedSuccessfully)
    {
        return DoAsyncAwaited(aquireTask);
    }

    return DoAsyncImpl()
}

async Task DoAsyncAwaited(Task task)
{
    await task.ConfigureAwait(false);
    await DoAsyncImpl().ConfigureAwait(false);
}

Task DoAsyncImpl()
{
   // ...
}
 benaadams
on 10 Nov 2017
But it wouldn't be WaitAsync(0), it'd be WaitAsync(). I see it as twice as fast as Wait(0) in the success case, and in the fail case it would need to call WaitAsync anyway.
stephentoub
on 10 Nov 2017
I assume the previous pattern was
Task DoAsync()
{
    var success = _semaphore.Wait(0);
    if (success)
    {
        return DoAsyncImpl();
    }
    else
    {
        return DoAsyncAwaited();
    }
}

async Task DoAsyncAwaited(Task task)
{
    await _semaphore.WaitAsync().ConfigureAwait(false);
    await DoAsyncImpl().ConfigureAwait(false);
}

Task DoAsyncImpl()
{
   // ...
}
With this benchmark:
```C#
using System;
using System.Threading;
using BenchmarkDotNet.Running;
using BenchmarkDotNet.Attributes.Jobs;
using BenchmarkDotNet.Attributes;
[InProcess]
public class Program
{
public static void Main() => BenchmarkRunner.Run
private static readonly SemaphoreSlim s_sem = new SemaphoreSlim(1, 1);

[Benchmark]
public static void WaitZero()
{
    for (int i = 0; i < 10; i++)
    {
        if (s_sem.Wait(0)) s_sem.Release();
    }
}

[Benchmark]
public static void WaitAsync()
{
    for (int i = 0; i < 10; i++)
    {
        if (s_sem.WaitAsync().IsCompletedSuccessfully) s_sem.Release();
    }
}
}
I get this result:
Method | Mean | Error | StdDev |
---------- |-----------:|---------:|---------:|
WaitZero | 1,083.1 ns | 5.417 ns | 4.802 ns |
WaitAsync | 423.3 ns | 2.080 ns | 1.946 ns |
And if I use WaitAsync, I can get away with just calling a wait method once, regardless of whether there's contention or not:
```C#
Task waitTask = s_semaphore.WaitAsync();
if (waitTask.IsCompletedSuccessfully)
{
    ...
    s_semaphore.Release();
    return Task.CompletedTask;
}
else
{
    return WaitAndProcessAsync(waitTask, ...);
}
The WaitAndProcessAsync method then just awaits the waitTask it was handed, rather than having to call WaitAsync() again.
stephentoub
on 10 Nov 2017
Wait does look like it does a spin before even trying to acquire?
As well as the actual acquire path being more complicated than the async path.
benaadams
on 10 Nov 2017
Wait does look like it does a spin before even trying to acquire?
Yeah, that looks like a perf bug introduced in https://github.com/dotnet/coreclr/commit/03bf95c8db9003a5925ca9383dca722a4c651e27#diff-e0962c2ab4c9e7938e811430bcaeae81R357
@kouvel, can you take a look?
stephentoub
on 10 Nov 2017
Opened https://github.com/dotnet/coreclr/issues/14980 for the erroneous spin.
stephentoub
on 10 Nov 2017
Well, I guess my pattern has just changed :) All that while I ate dinner. Good work
Drawaes
on 10 Nov 2017
stephentoub
on 2 Dec 2017
Related issues
 noahfalk
·
3Comments
 omajid
·
3Comments
 sahithreddyk
·
3Comments
 v0l
·
3Comments
 Timovzl
·
3Comments
Most helpful comment
But it wouldn't be WaitAsync(0), it'd be WaitAsync(). I see it as twice as fast as Wait(0) in the success case, and in the fail case it would need to call WaitAsync anyway.